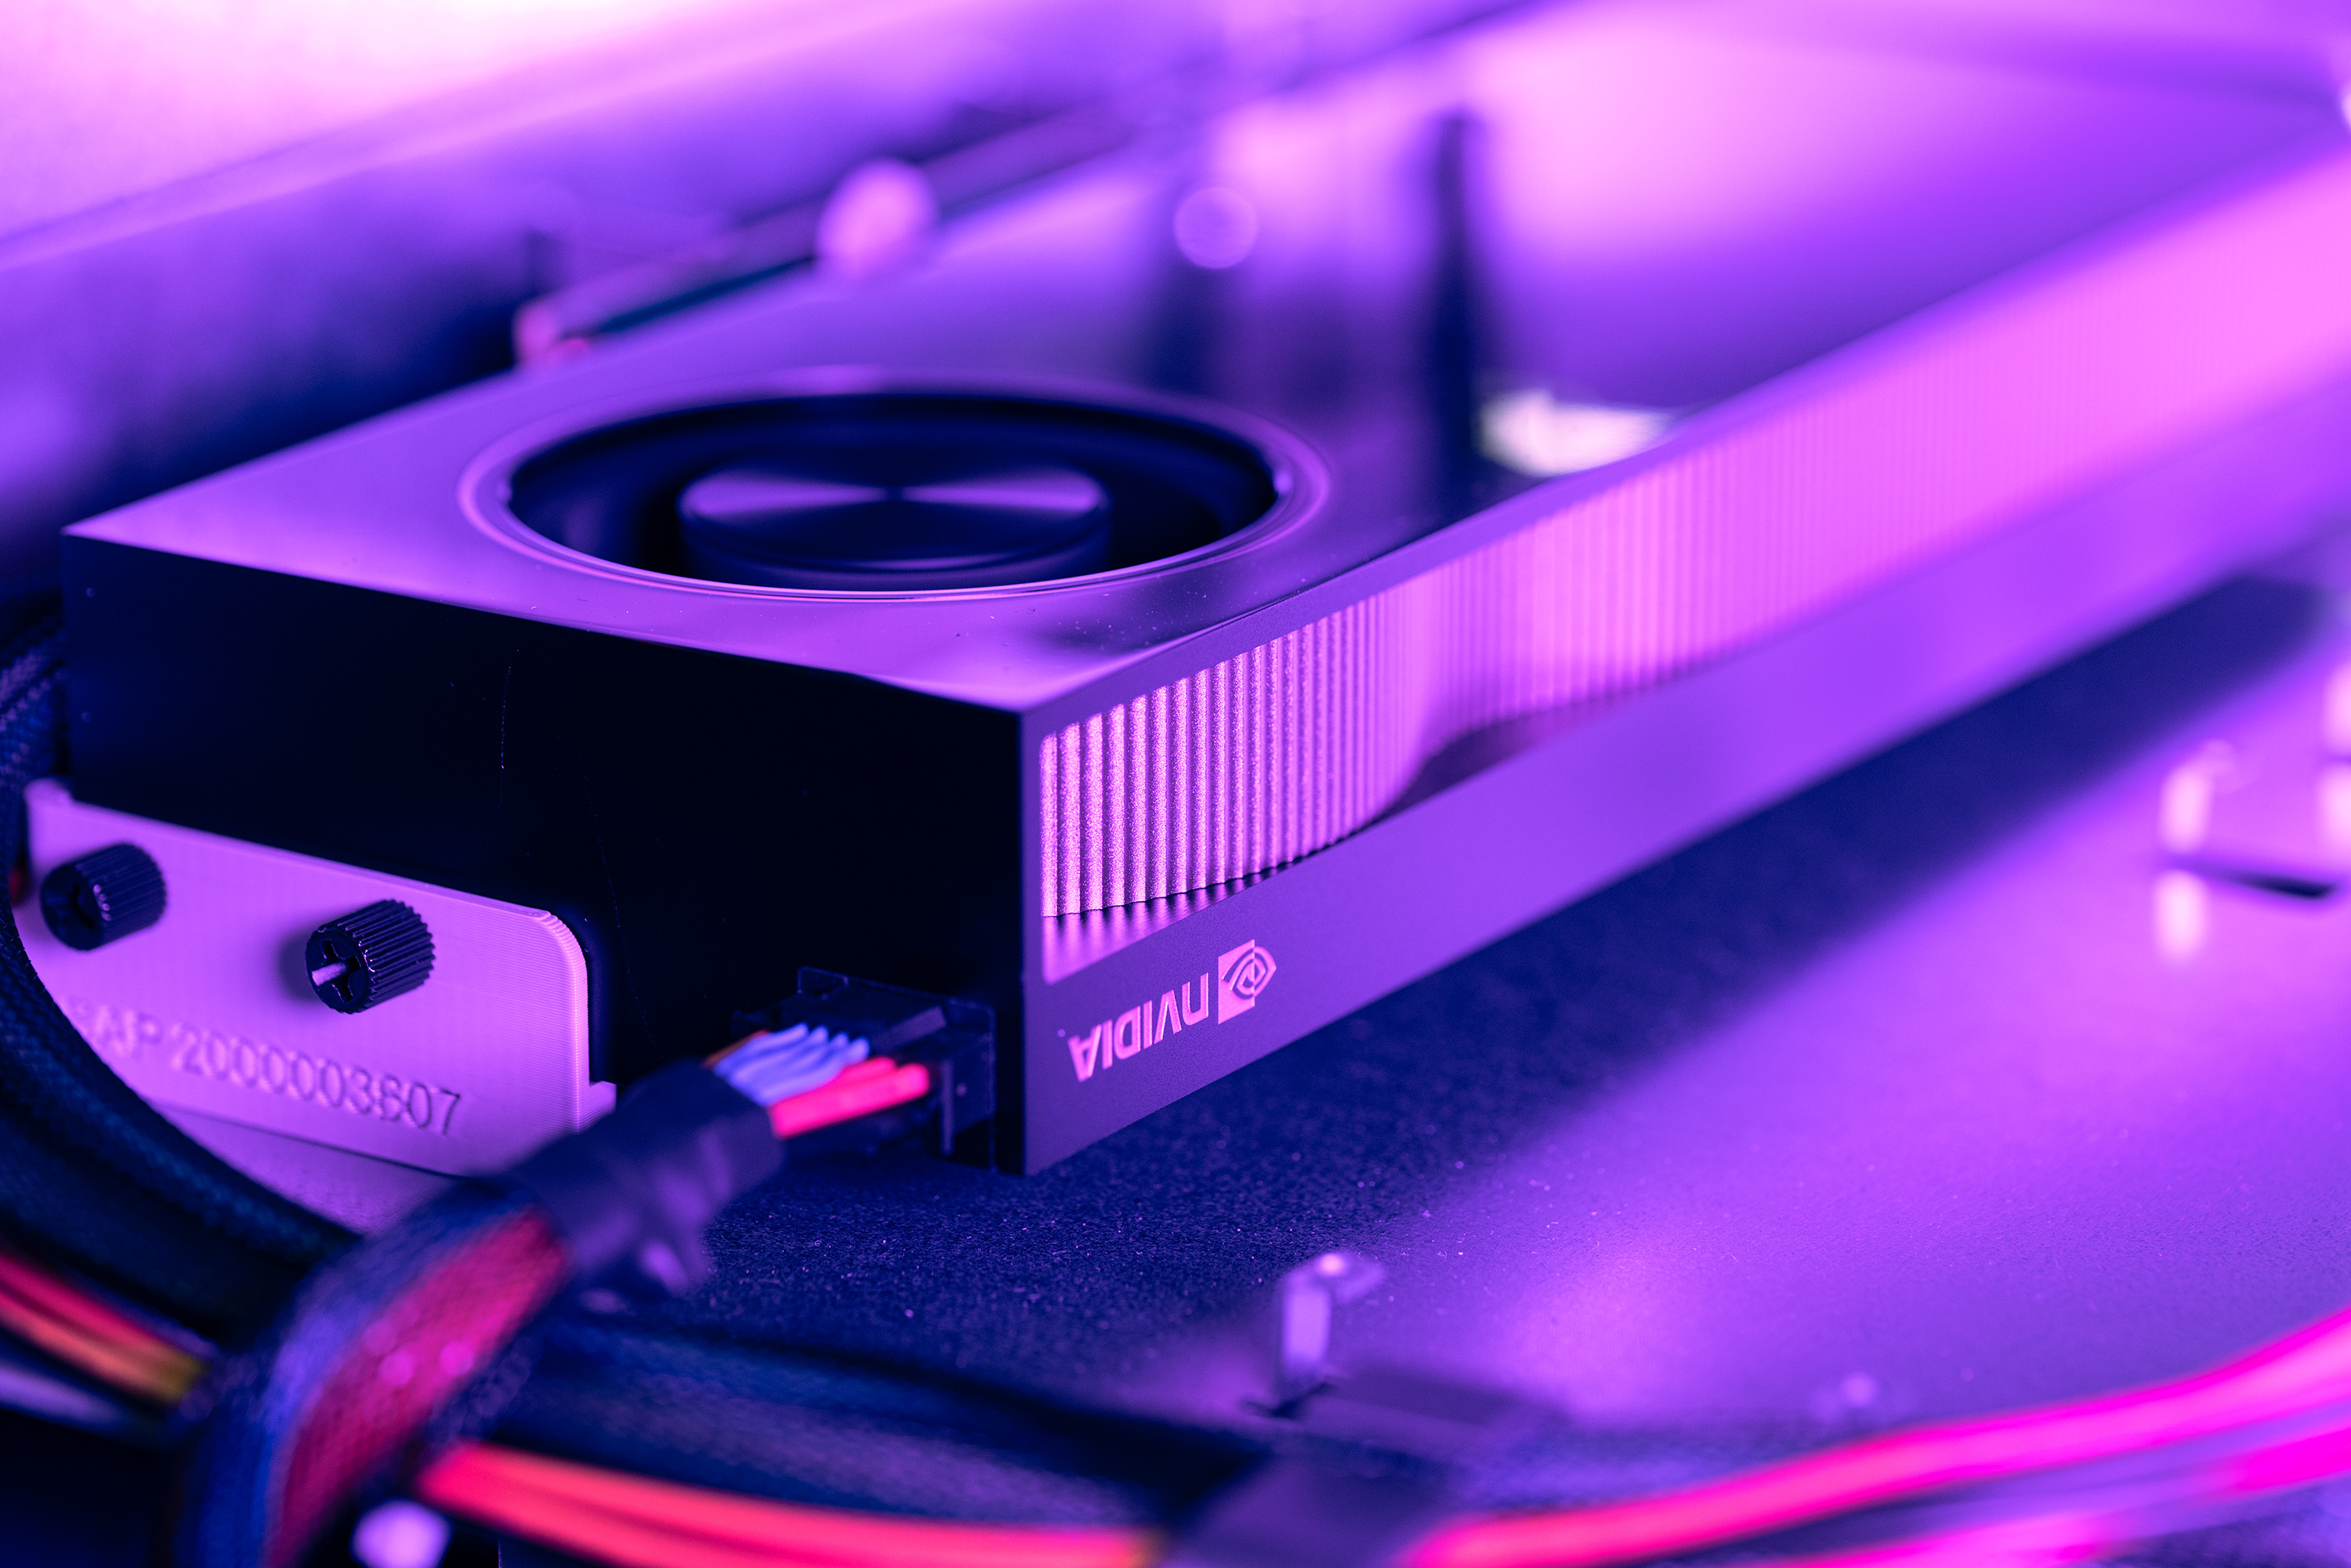
With the GEX430, hosting provider Hetzner is expanding its portfolio to include its first multi-GPU server. The new model is equipped with four NVIDIA RTX PRO™ 6000 Blackwell Max-Q GPUs and a total of 384 GB of GDDR7 ECC graphics memory. This high-performance dedicated server is specifically designed for businesses and professional users who require high computing power for AI training, inference of large language models (LLMs), fine-tuning, and demanding rendering and simulation tasks.
The four high-end GPUs make it possible to run particularly memory-intensive AI models and operate multiple models in parallel. This allows companies to consolidate different AI applications onto a single server. For example, one language model can be used for customer support, while another assists developers with programming and a third automatically processes incoming requests. These tasks can be distributed across the individual GPUs.
Available graphics memory also plays a central role in AI inference. Memory requirements increase significantly, especially when handling a high volume of concurrent requests. With a total of 384 GB of VRAM, the GEX430 offers extensive resources for the delivery of large language models and the simultaneous service of numerous users. This benefits, for example, companies that use AI chatbots in customer support or operate internal knowledge assistants for their employees.
“Especially when it comes to AI inference, graphics memory is just as crucial as computing power. The more requests a model processes simultaneously, the more memory it generally requires. With four GPUs and a total of 384 GB of VRAM, the GEX430 offers plenty of headroom for demanding AI applications. Companies can use it, for example, to run multiple language models in parallel or to provide their AI services for a large number of concurrent users,” says Stefan Weiberg, Product Manager at Hetzner.
Each of the four NVIDIA RTX PRO™ 6000 Blackwell Max-Q GPUs features 96 GB of GDDR7 ECC VRAM and supports modern AI technologies such as fifth-generation Tensor Cores, fourth-generation RT Cores, and FP4. The GPU configuration is complemented by an Intel® Xeon® Gold 5412U processor with 24 cores and 48 threads, 128 GB of DDR5 ECC registered memory, and two 1.92 TB Datacenter Edition (Gen4) NVMe SSDs.
With the GEX430, companies can run open-weight AI models such as GLM, Mistral, or Qwen on dedicated hardware within the EU without having to rely on external AI platforms. When configured appropriately, sensitive information such as internal documents, customer data, or source code remains within the company’s own server environment. This creates favorable conditions for implementing individual data protection and compliance requirements. At the same time, users retain control over the models used, their data, and the configuration of the infrastructure.
The Hetzner GEX430 is available for € 3,599.00 / $ 4,199.00 per month, including an IPv4 address. The one-time setup fee is also € 3,599.00 / $ 4,199.00.
Further information is available at https://www.hetzner.com/dedicated-rootserver/matrix-gpu/
All prices without VAT.