Whether we are talking about AI chatbots or alarmingly realistic videos and images created artificially, AI dominates many of today’s major tech discussions. And it looks like that will remain the case for years to come.
But when we talk about AI, we also need to talk about GPUs. More specifically, we need to talk about GPU servers. They form the backbone of the AI wave that is reshaping the world and handle a huge share of the computational workload.
But that is not all: graphics cards still serve their original purpose in graphics-intensive work, such as complex 3D simulations and large-scale video rendering.
In this article, we explain what a GPU server is, where its strengths lie, and which tasks truly benefit from one.
What is a GPU server?
A traditional server and its CPU handle many different tasks: databases, web servers, web hosting, or cloud services. CPUs are especially ideal when processes need to run quickly, flexibly, and with the lowest possible latency. Most server services do not need a GPU at all. GPU servers are therefore designed for more specialized requirements.
The major advantage of a GPU is massive parallel data processing. A CPU works with a smaller number of very powerful cores. A GPU, on the other hand, has a very large number of compute units that can perform many more operations at the same time.
Think of the processor as a sports car. It is small, agile, and can take every corner at high speed. But it only has room for two people — or, in this analogy, data units. The GPU is more like a city bus. It follows simpler routes without sharp turns at a moderate speed, but it can carry 50 people at once.
Still, the GPU does not replace the processor. Both handle different tasks. The CPU controls processes, prepares data, and coordinates workflows within the system. The GPU then takes over the heavy computational workload. Only when they work together do you get a server that can handle the specific requirements of GPU-based tasks.

What you need a GPU server for
Artificial intelligence: the main driver
GPUs are mainly used in AI. Large language models (LLMs), AI image recognition, and other demanding AI models need to process large amounts of data and many computing operations in parallel — an ideal task for graphics cards. When building an AI model, there are three main phases. In each phase, the GPU server handles a different type of workload:
Training: In pretraining, you train a model from scratch. This means feeding it large amounts of data until it develops a general understanding. This process requires enormous computing power, comes with high costs, and can take weeks or months. It is typical for research institutions, Big Tech companies, and governments. Post-training improves reasoning capabilities and develops the typical chat behavior you know from well-known LLMs. The result is called a base model.
Fine-Tuning: Fine-tuning builds on the initial large-scale training phase. Companies can adapt an existing base model with their own proprietary data, turning it into an expert for a specific domain. The model then responds more precisely and consistently. In some cases, a smaller fine-tuned model can solve certain tasks better than a large model without fine-tuning — while also reducing costs.
Fine-tuning places a moderate demand on memory and compute resources, making it worthwhile for companies of all sizes.
Inference: This phase describes the actual use of the model. At this point, the model is no longer being trained. A classic example is a chatbot that answers support questions on a website.
Rendering, CAD and visualization
Originally, GPUs belonged to the world of graphics. Moving images can be broken down into many small subtasks, which the graphics card then processes. A powerful GPU can dramatically reduce rendering time. Large video renders and detailed 3D scenes benefit the most. CAD programs for technical drawings and engineering designs, as well as demanding image and video editing workflows, also run noticeably more smoothly.
Scientific simulations
Weather models, molecular simulations, and thermodynamic calculations all have something in common: as with AI, they generate massive amounts of data that need to be processed in parallel. The key distinction is that these models are dominated by mathematical computations. A powerful GPU can significantly accelerate these calculations.
What matters when it comes to hardware
VRAM as a key metric
Not every GPU is the same. The generation and model already tell you a lot about which tasks a server is suited for — whether AI, rendering, or visualization.
One of the most important metrics is VRAM, the GPU’s dedicated memory. It determines how much data the GPU can process directly. This applies to both AI models and complex 3D scenes, because everything the GPU needs to process at the same time must fit into its graphics memory. If the VRAM is too small, even the fastest GPU will not help.
As a rough guide:
- Up to around 40 GB of VRAM: suitable for small to medium-sized models, inference, and many GPU-accelerated workloads such as image or video processing and CAD.
- Around 40 to 100 GB of VRAM: better for larger models and many fine-tuning scenarios. This range also allows for larger batch sizes and longer contexts. In other words, you can process more data at once, and the model can handle larger inputs at the same time.
- More than 100 GB of VRAM: useful for very large models, multi-GPU setups, and specialized use cases.

CPU, RAM and storage as supporting components
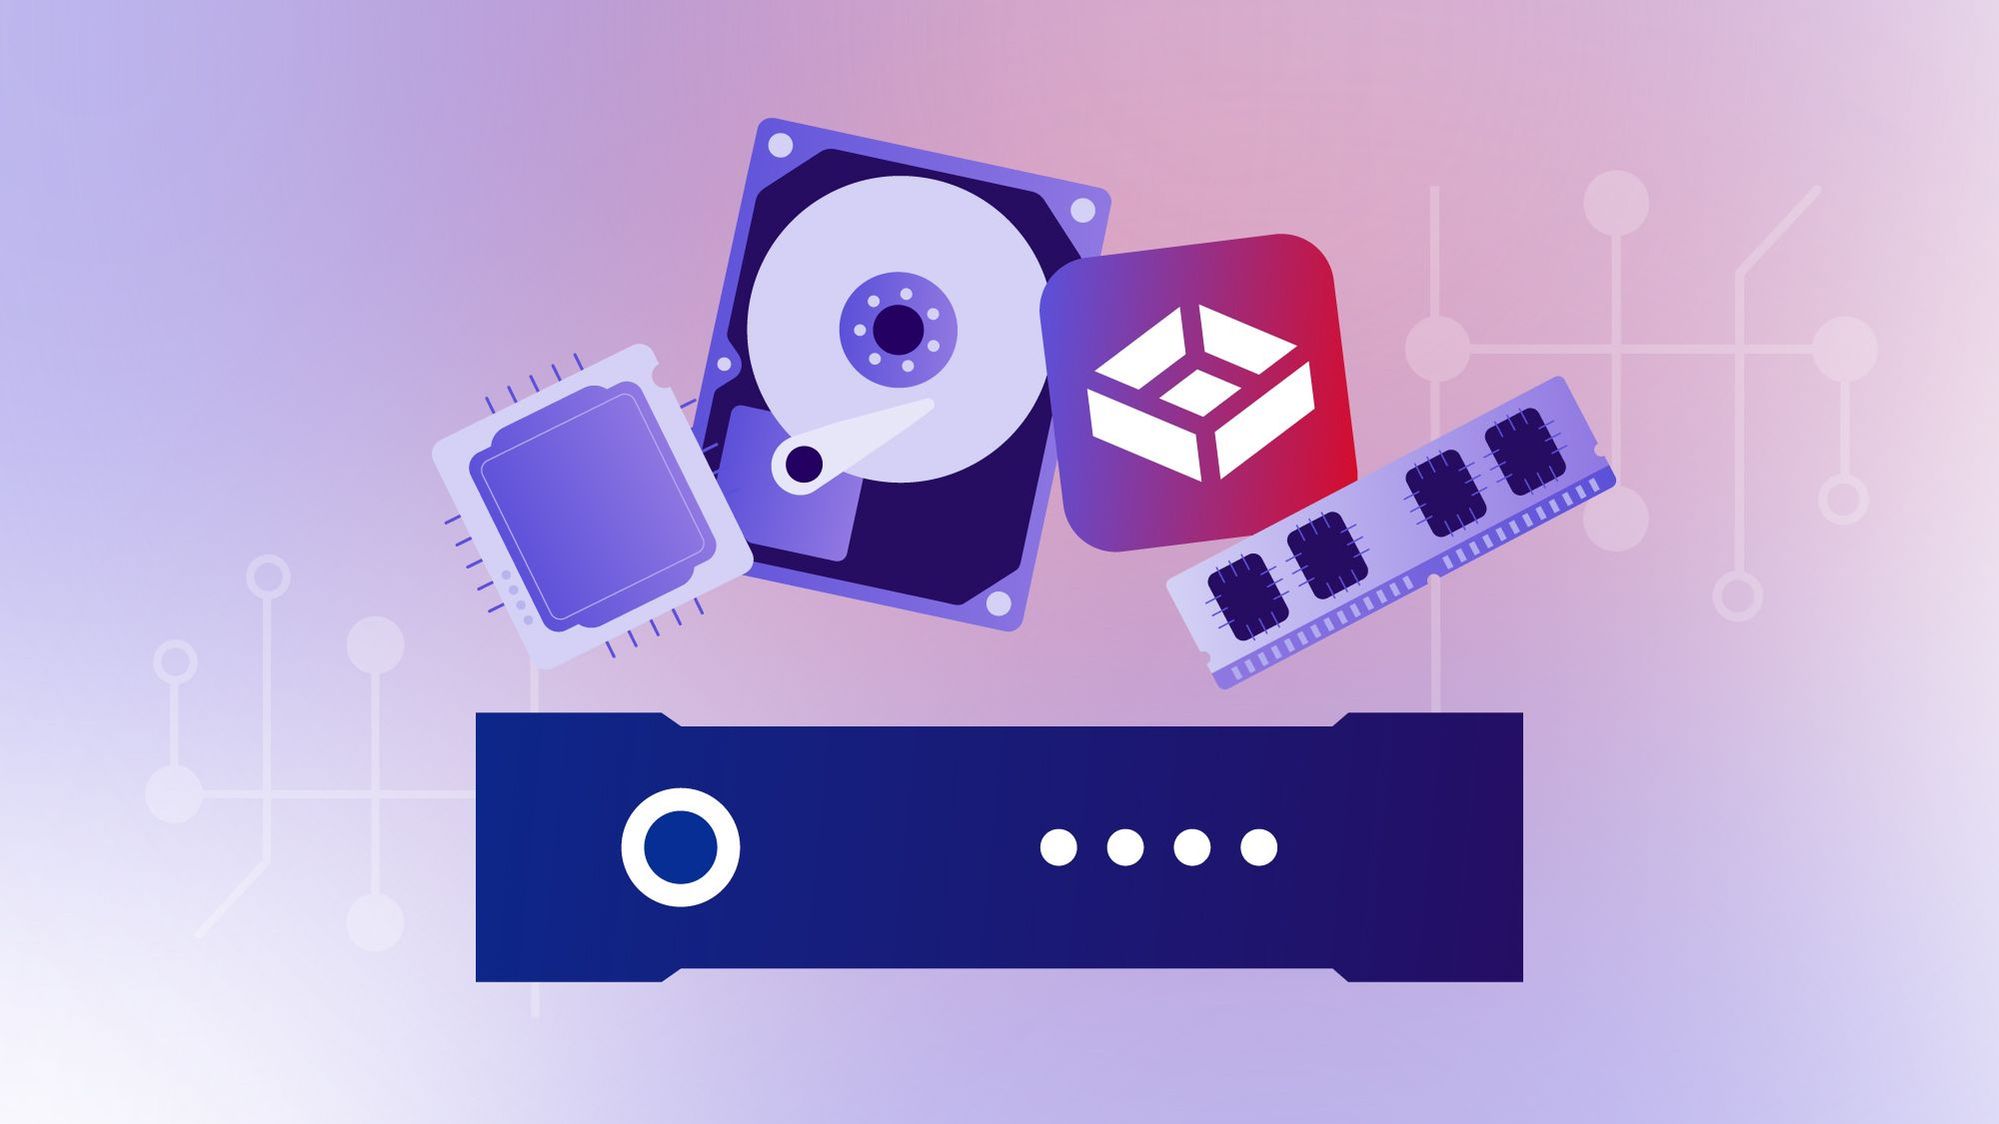
But the GPU alone does not determine performance. The CPU, RAM, and storage also need to match the workload. The CPU controls processes, prepares data, and supplies the GPU with new tasks.
RAM and fast SSDs make sure that data is available in time and that the workflow does not stall. What matters is not only how much storage is available, but also how quickly the GPU can access it. That is why NVMe SSDs are the right choice. ECC RAM also detects and corrects memory errors, which makes it especially relevant in scientific and professional environments.
CUDA, Tensor Cores and RT Cores
Our GPU servers use NVIDIA graphics cards. And when you talk about NVIDIA, you also need to talk about CUDA, which is NVIDIA’s software and development platform. It is especially widespread in GPU computing. Many AI frameworks, such as PyTorch and TensorFlow, rely on it — as does rendering software.
But there is an important distinction: CUDA is the software platform, while CUDA Cores are the physical compute units on the GPU.
Besides CUDA Cores, NVIDIA GPUs also house Tensor Cores and RT Cores. Tensor Cores are specialized hardware units designed to accelerate matrix operations, which are the core computations in modern AI models. RT Cores, on the other hand, specialize in ray tracing, a technique that simulates realistic light behavior. This means they mainly accelerate rendering tasks and other graphically demanding visualizations.
Find the right GPU server
Whether single- or multi-GPU: The choice is yours. Find the server that fits your AI workload.
Which GPU server is right for you?
AI, and therefore GPUs, are developing at tremendous speed. They handle a wide range of tasks and have become part of many company workflows. As a result, choosing the right GPU server is becoming a crucial question for more and more businesses.
However, more performance does not automatically mean better results. Anyone looking to deploy a GPU server should have a clear understanding of their requirements. How large are the data sets? How much VRAM is needed? And what tasks should the GPU handle? Those who can answer these questions already have a solid foundation for choosing the right hardware.